Go further

Bigger models, same blocks.

A model that writes

Teach a small model to write like Shakespeare.

Give it the start of a text, and it writes on.

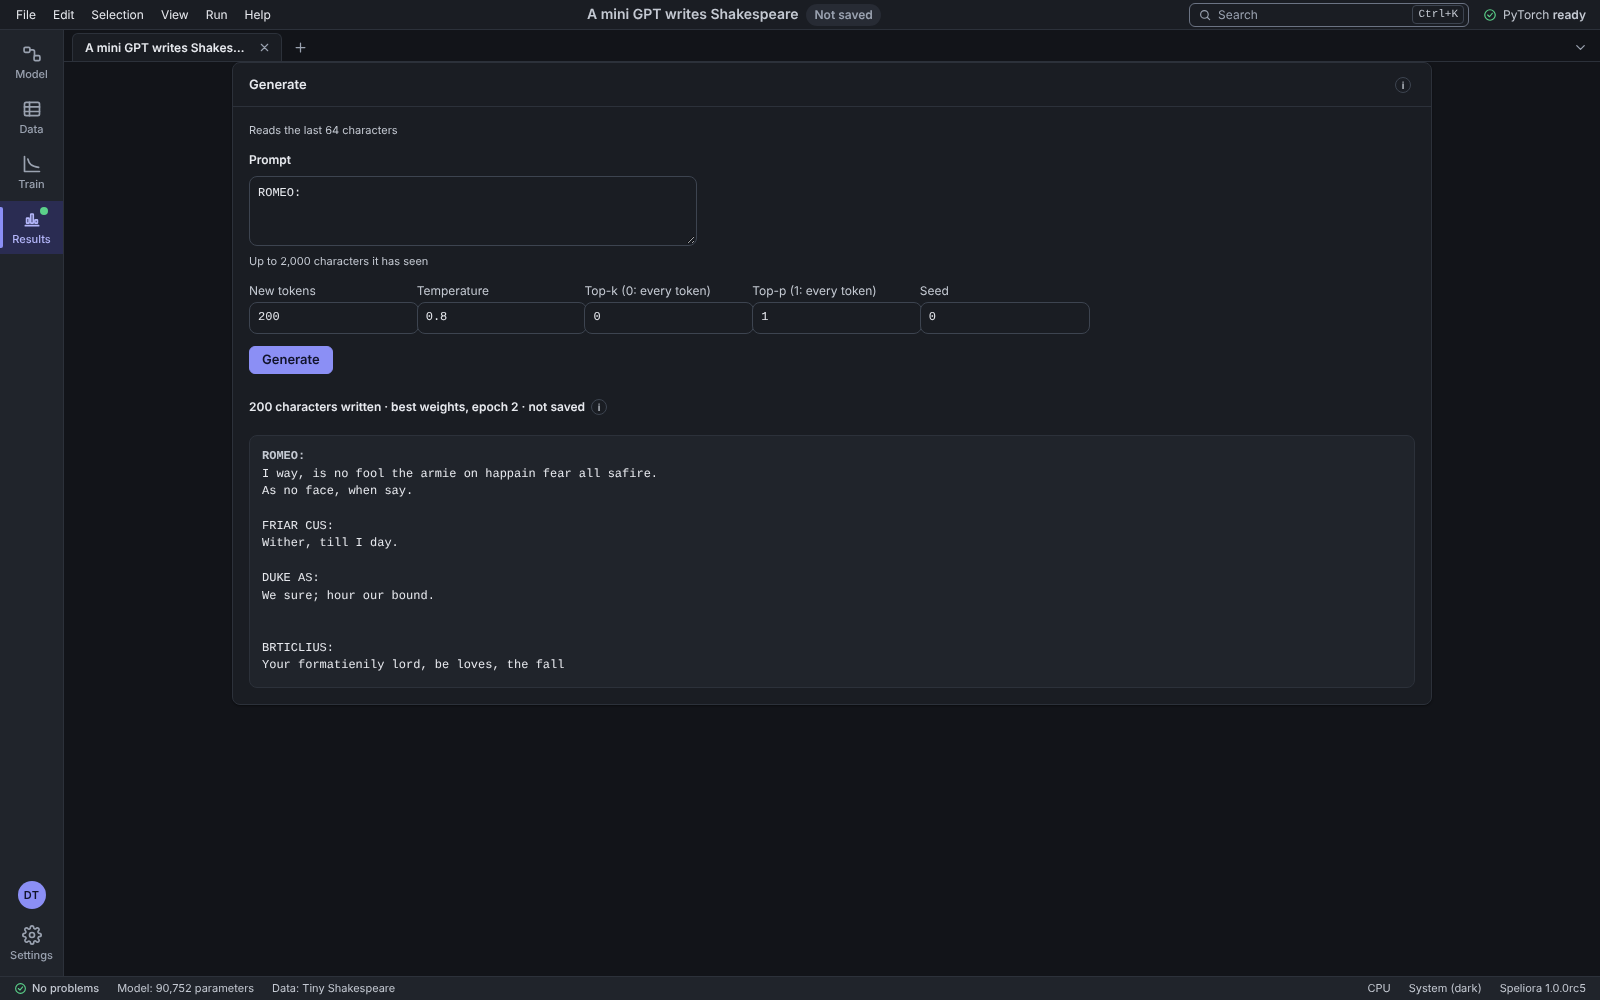
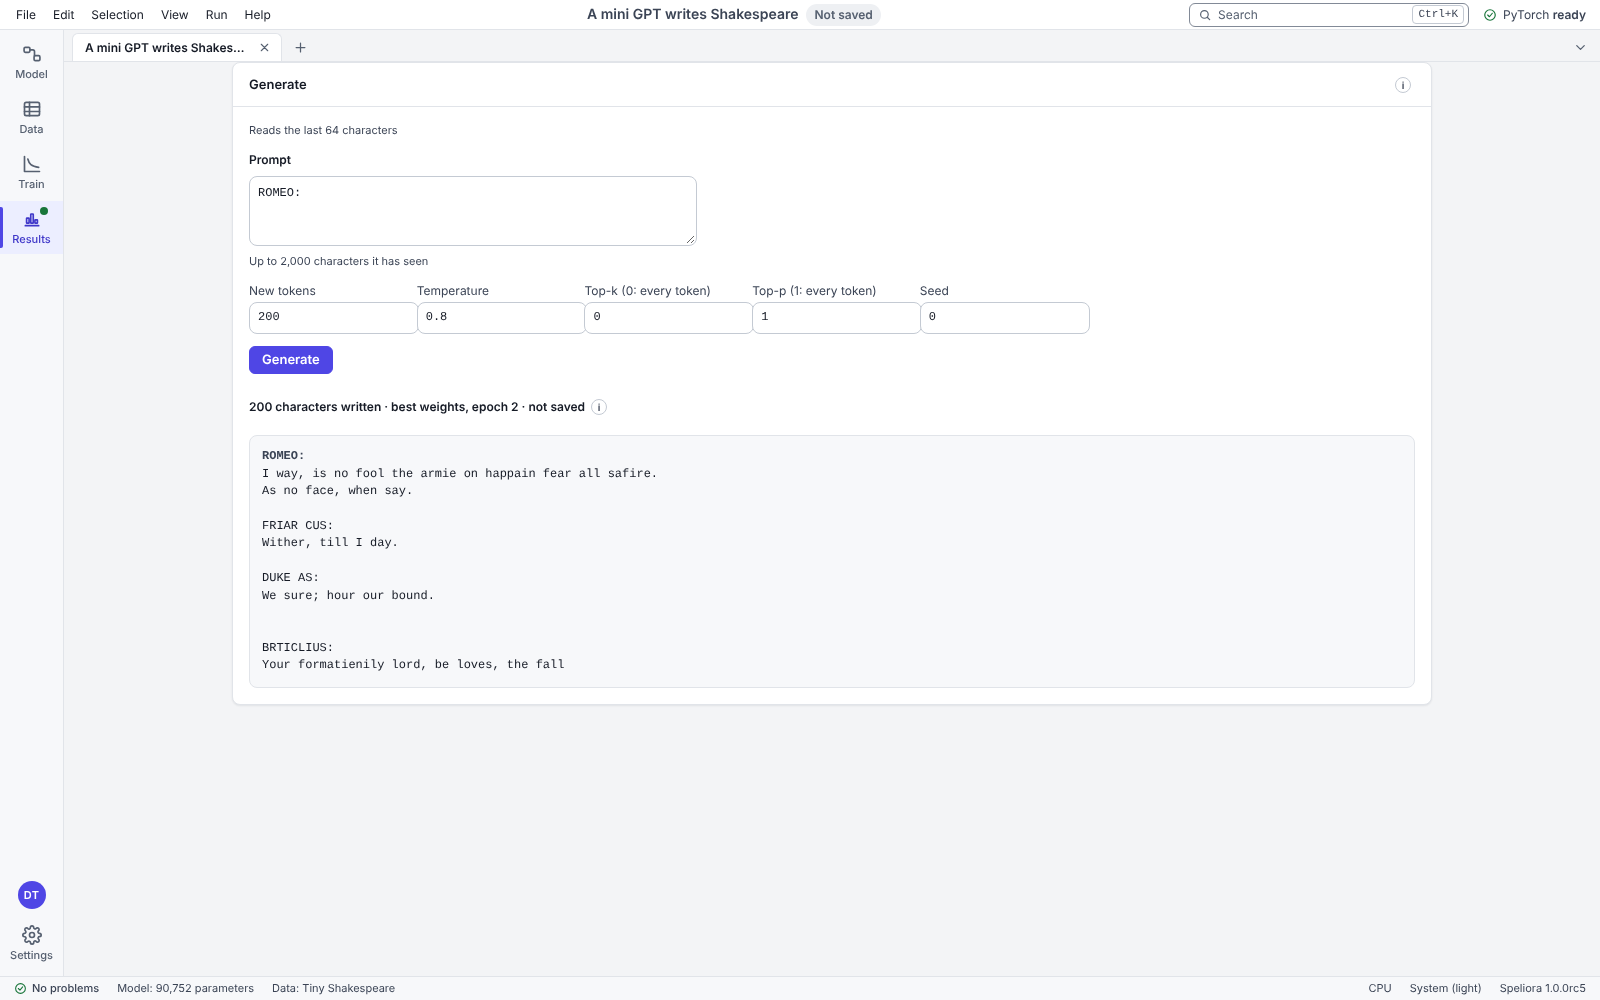
Prompt ROMEO:
ROMEO:
I way, is no fool the armie on happain fear all safire.
As no face, when say.

FRIAR CUS:
Wither, till I day.

DUKE AS:
We sure; hour our bound.


BRTICLIUS:
Your formatienily lord, be loves, the fall
Not Shakespeare yet, but shaped like a play.
Generate with the mini GPT trained on Tiny Shakespeare: the prompt ROMEO: and 200 characters the model wrote after it, in the shape of a play, with speakers such as FRIAR CUS and DUKE AS.Generate with the mini GPT trained on Tiny Shakespeare: the prompt ROMEO: and 200 characters the model wrote after it, in the shape of a play, with speakers such as FRIAR CUS and DUKE AS.Generate with the mini GPT trained on Tiny Shakespeare: the prompt ROMEO: and 200 characters the model wrote after it, in the shape of a play, with speakers such as FRIAR CUS and DUKE AS.

Image models

See where an image model looks.

See which parts of an image it uses.
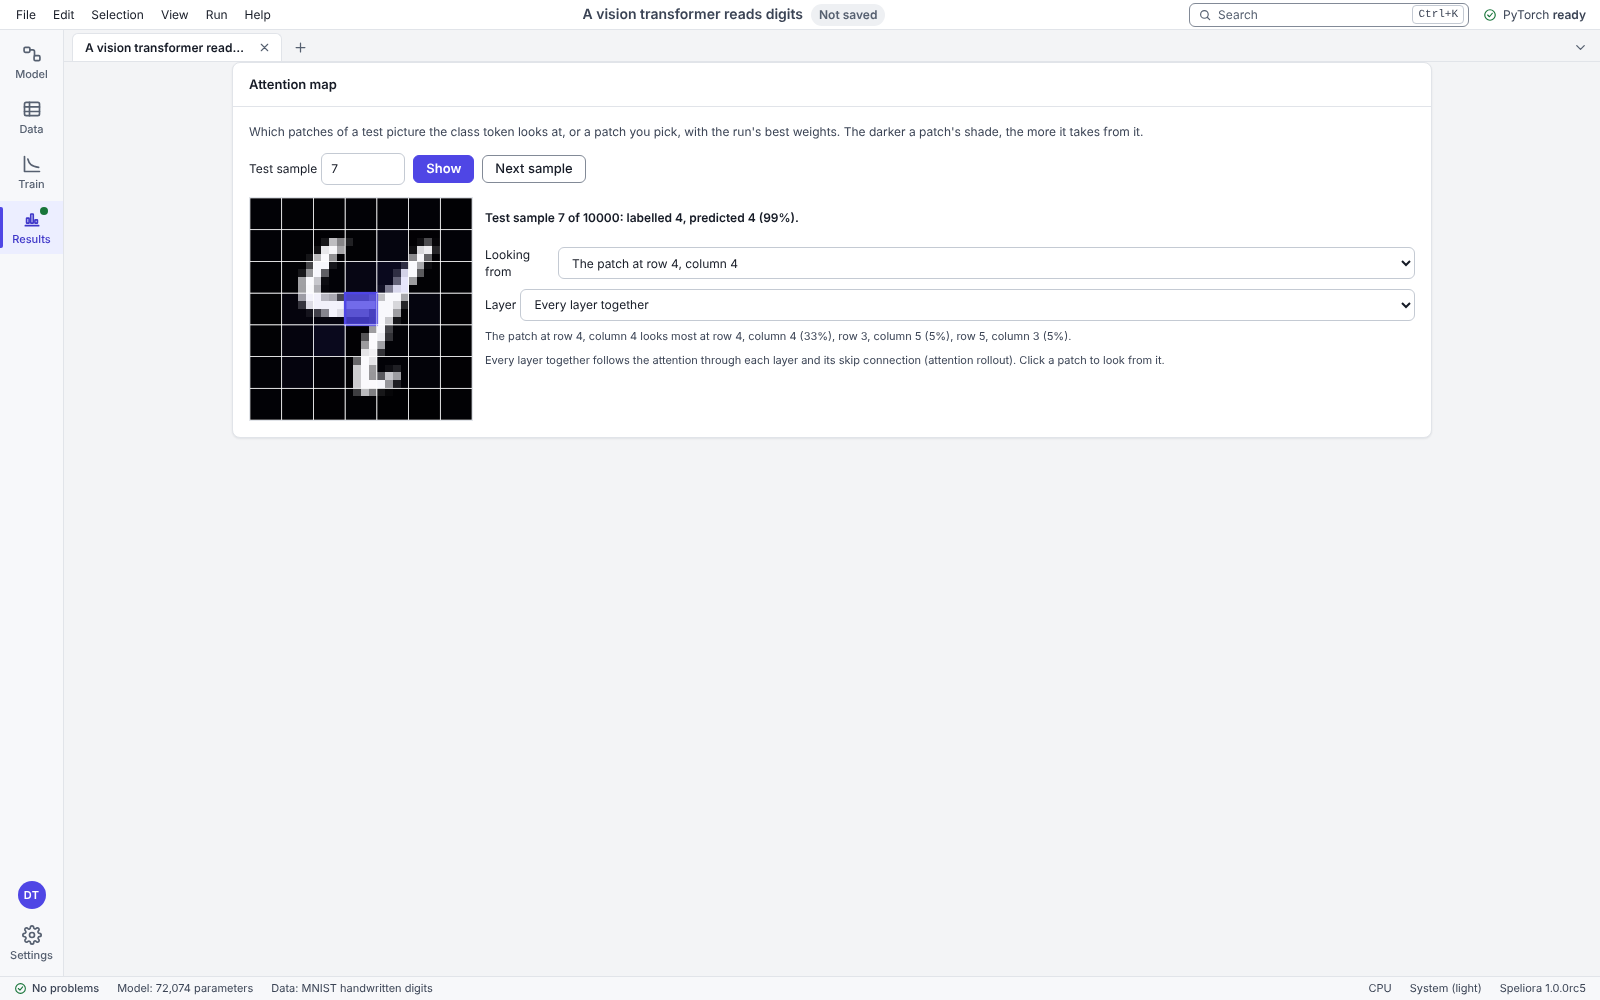
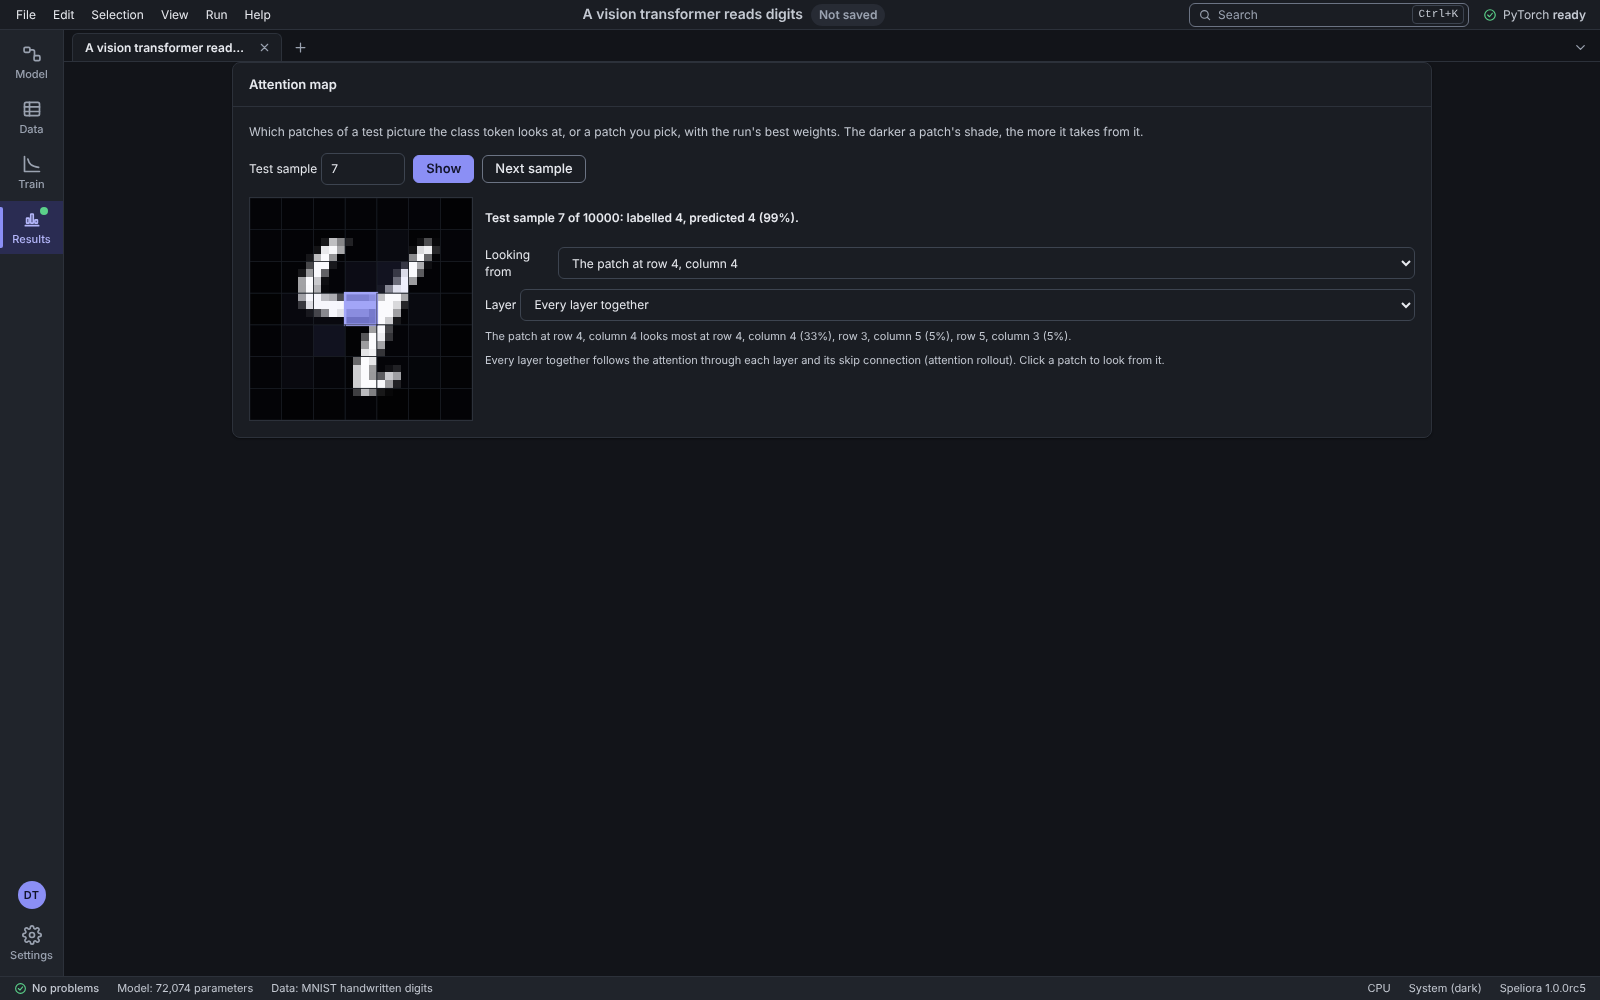
A vision transformer's attention for test sample 7, a handwritten 4 that the model predicts as 4 with 99% confidence: the attention from the patch at row 4, column 4, laid over the digit's patches.A vision transformer's attention for test sample 7, a handwritten 4 that the model predicts as 4 with 99% confidence: the attention from the patch at row 4, column 4, laid over the digit's patches.A vision transformer's attention for test sample 7, a handwritten 4 that the model predicts as 4 with 99% confidence: the attention from the patch at row 4, column 4, laid over the digit's patches.

Ready-trained models

Start from a ready-trained model.

See its size and licence first. Then train only a small add-on to it (LoRA).
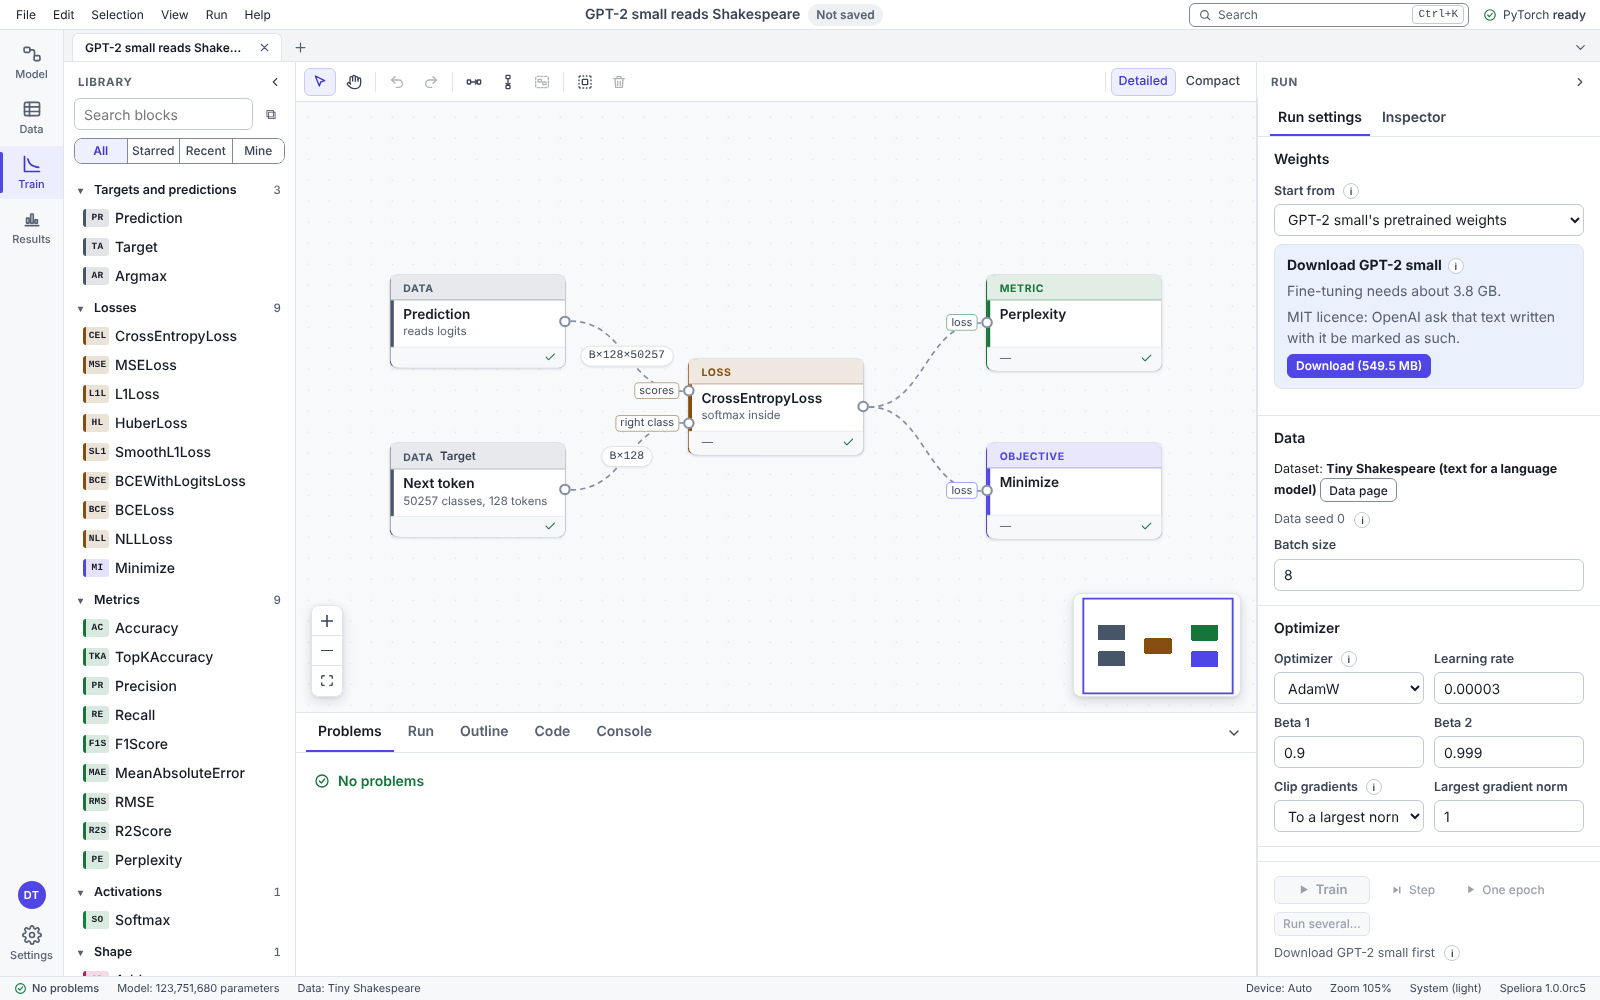
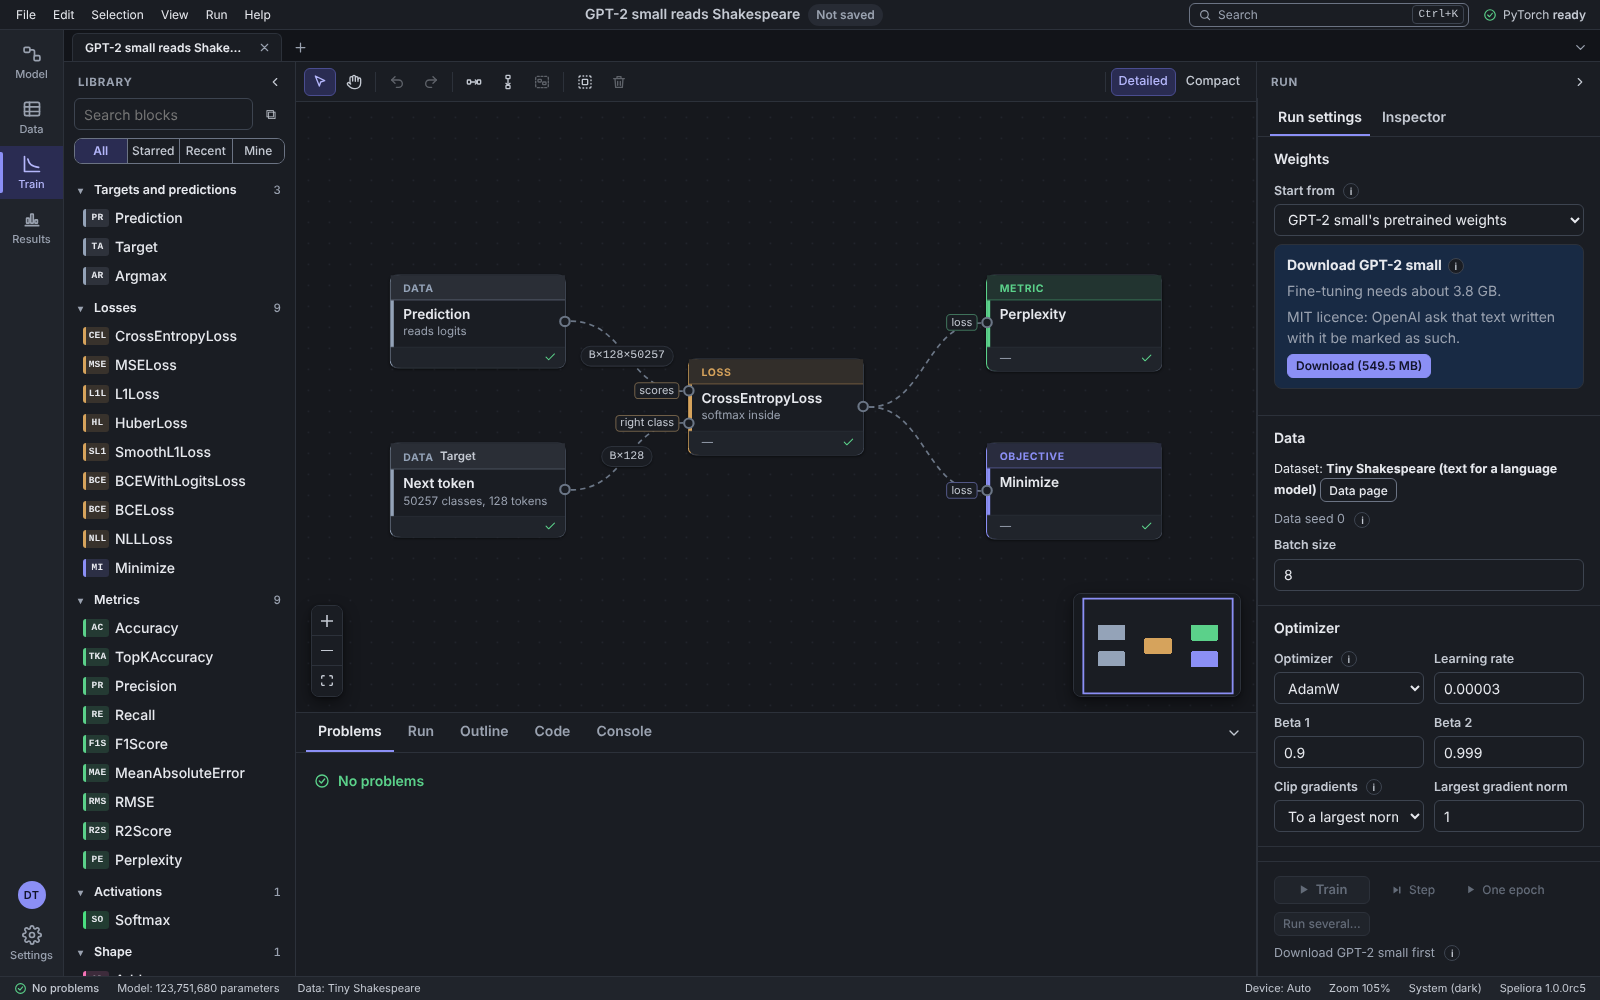
Starting from GPT-2 small: a card with its source, licence and size (124 million weights, 549.5 MB to download), the memory fine-tuning needs (about 3.8 GB), and a Download button. Nothing downloads until it is pressed.Starting from GPT-2 small: a card with its source, licence and size (124 million weights, 549.5 MB to download), the memory fine-tuning needs (about 3.8 GB), and a Download button. Nothing downloads until it is pressed.Starting from GPT-2 small: a card with its source, licence and size (124 million weights, 549.5 MB to download), the memory fine-tuning needs (about 3.8 GB), and a Download button. Nothing downloads until it is pressed.
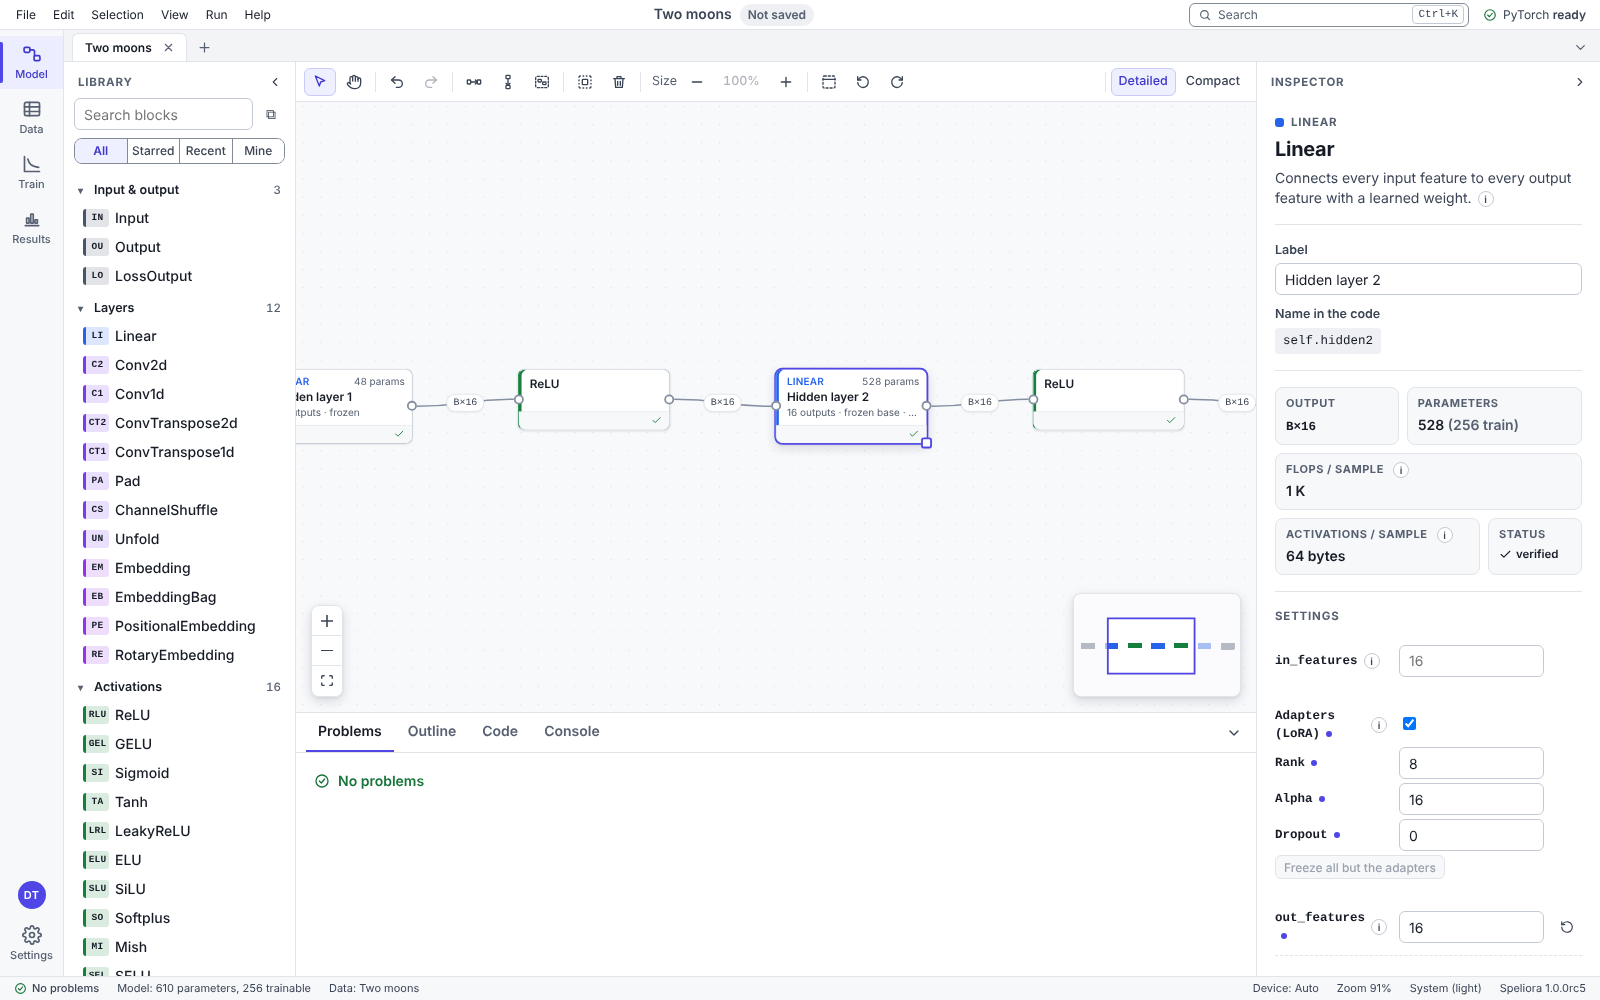
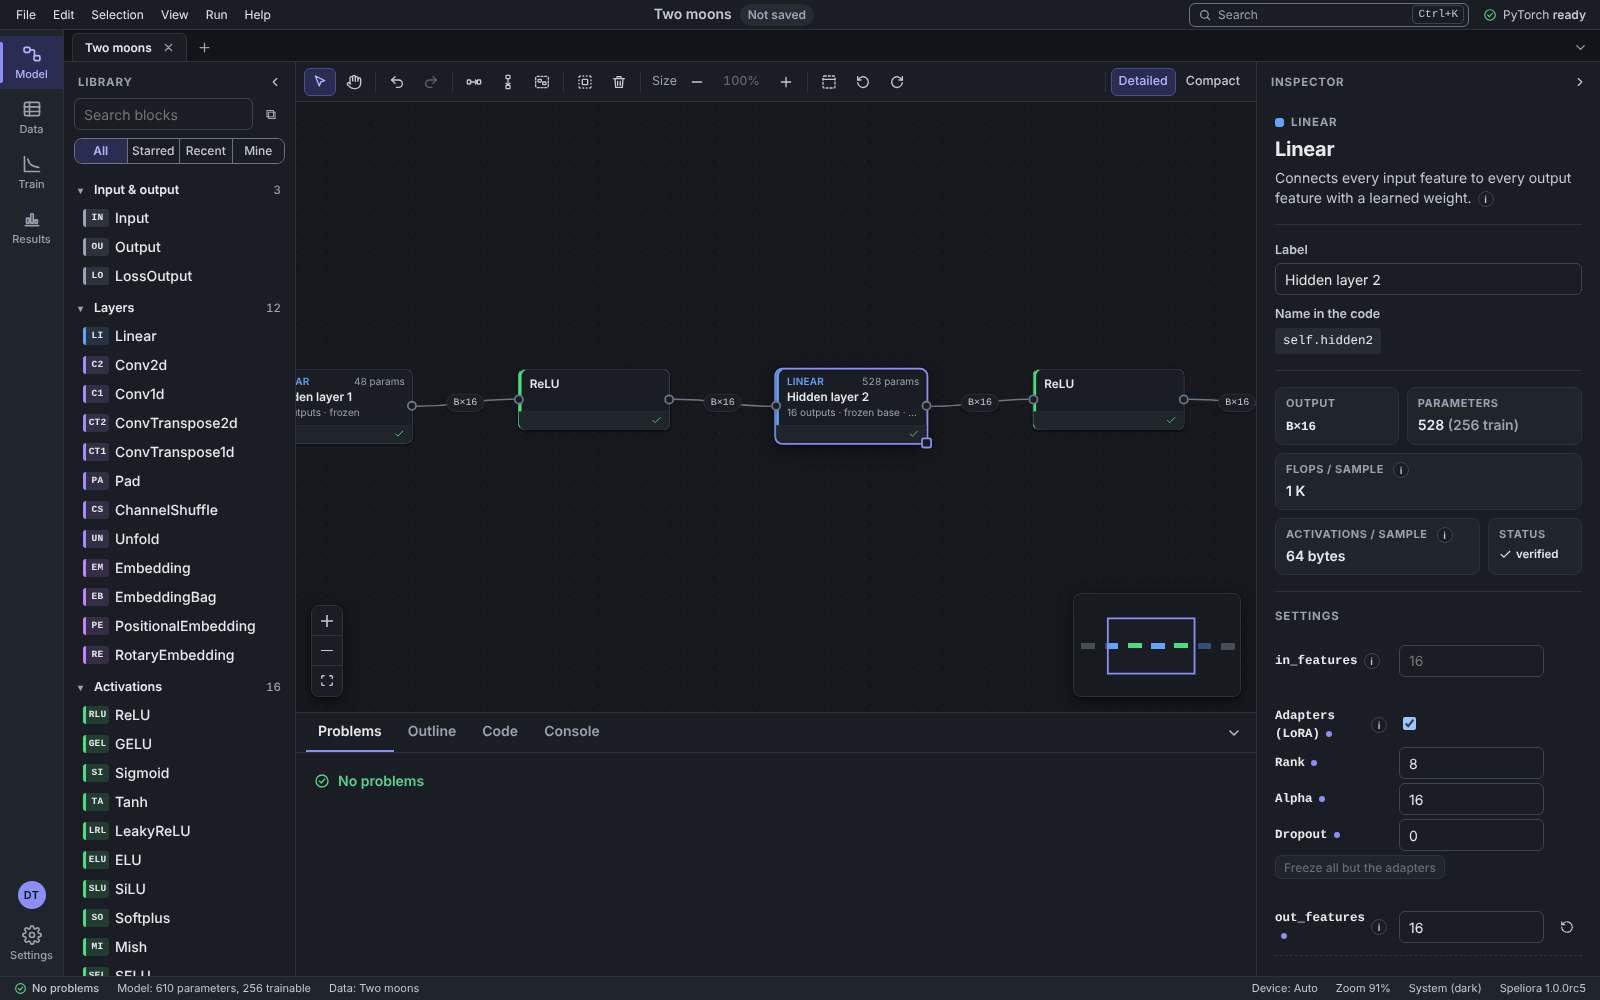
LoRA on a block of the Two moons model: Hidden layer 2 with a LoRA adapter of rank 8 and alpha 16, 528 parameters of which 256 train; the whole model has 610 parameters, 256 of them trainable.LoRA on a block of the Two moons model: Hidden layer 2 with a LoRA adapter of rank 8 and alpha 16, 528 parameters of which 256 train; the whole model has 610 parameters, 256 of them trainable.LoRA on a block of the Two moons model: Hidden layer 2 with a LoRA adapter of rank 8 and alpha 16, 528 parameters of which 256 train; the whole model has 610 parameters, 256 of them trainable.

Hugging Face

Use a public Hugging Face dataset.

Nothing downloads until you click.
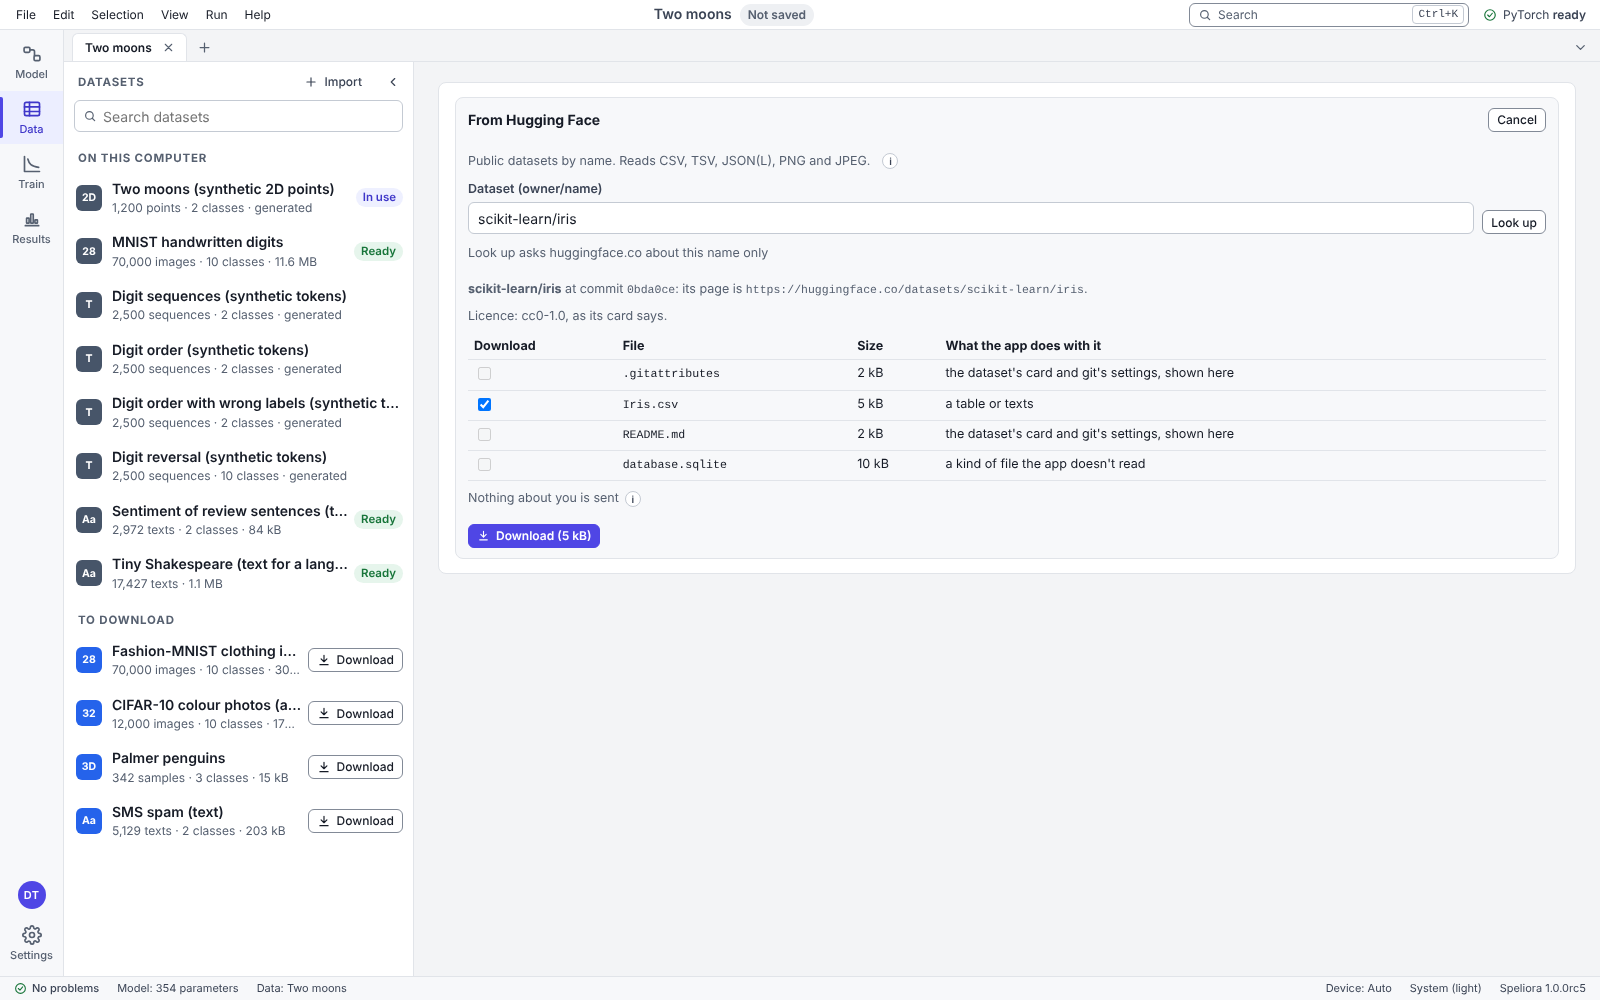
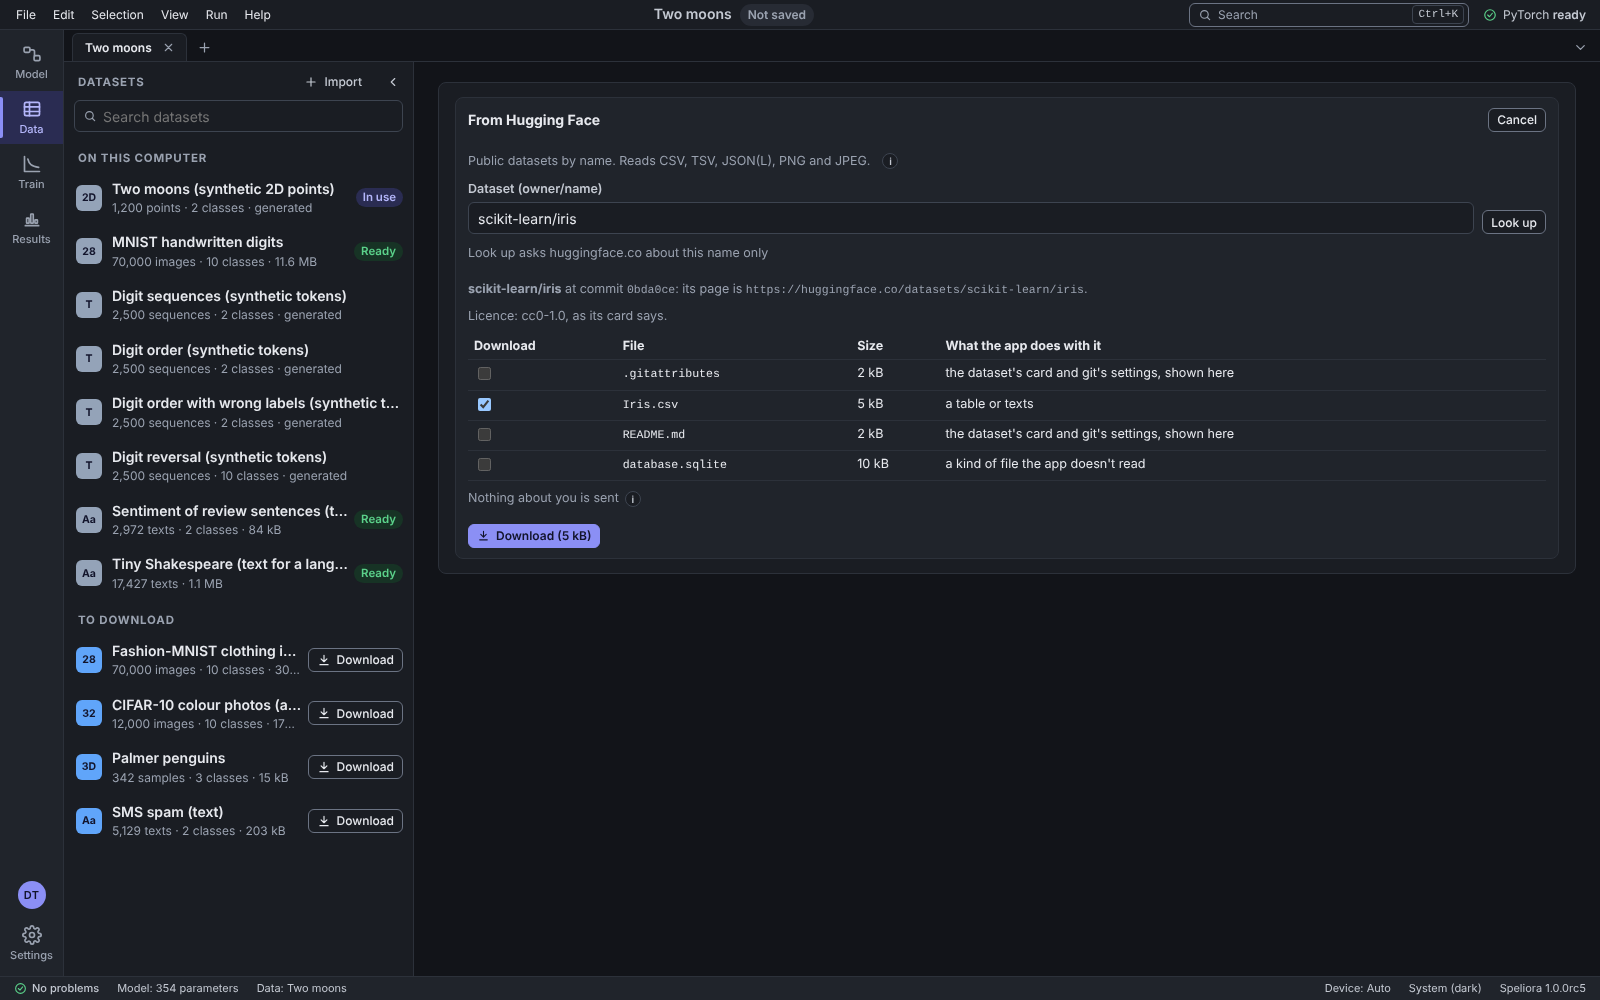
A Hugging Face lookup of scikit-learn/iris before any download: its commit, its licence (cc0-1.0), each file with its size and what the app does with it, and a Download button for the chosen 5 kB.A Hugging Face lookup of scikit-learn/iris before any download: its commit, its licence (cc0-1.0), each file with its size and what the app does with it, and a Download button for the chosen 5 kB.A Hugging Face lookup of scikit-learn/iris before any download: its commit, its licence (cc0-1.0), each file with its size and what the app does with it, and a Download button for the chosen 5 kB.

Also inside.

Mixture of experts, models that fill in hidden words, a profiler that times each block, and tokenizers.

The download is coming soon.

The Windows app is getting ready for its first release.

Windows download coming soonWhat the computer will need